Crash / Freeze
A crash happens when a program or your entire computer suddenly stops working and closes or shows an error message.
A freeze is when everything becomes unresponsive: you can see the screen, but nothing responds to clicks or key presses. Both are frustrating but usually fixable. They can be caused by software bugs, insufficient memory, hardware issues, or conflicts between programs.
What it looks like
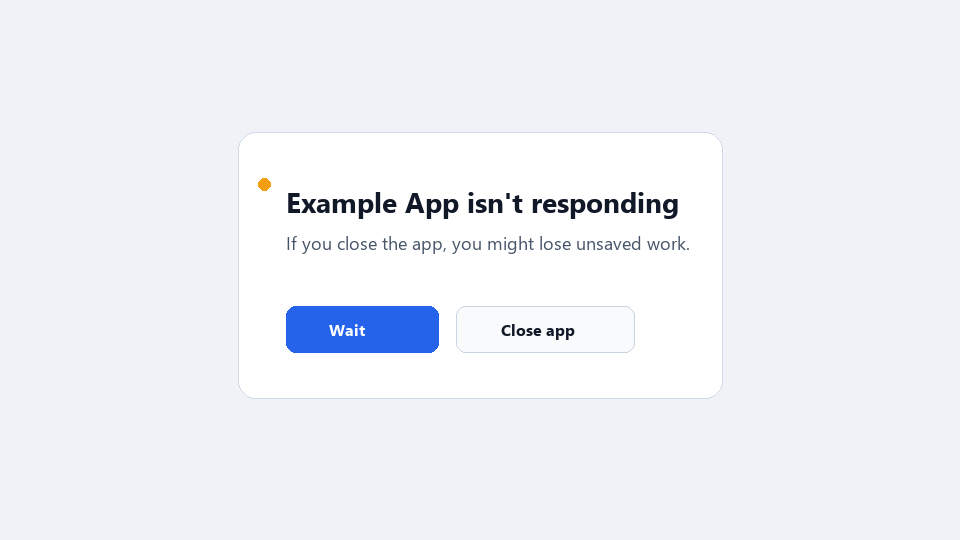
Crash / Freeze, explained at three levels
At home
A crash is when a program suddenly stops working and closes itself, sometimes showing an error message. A freeze is when your screen gets stuck and nothing responds, no matter what you click. Crashes are usually caused by a bug in the software, while freezes can happen when your computer runs out of memory or a program gets stuck in a loop. The simplest fix is usually to close the stuck program or restart your computer.
At work
In the workplace, crashes and freezes cause lost productivity and can lead to data loss if work was not saved. Employees should know how to use Task Manager to close frozen applications without restarting the entire computer. IT departments track crash patterns to identify unreliable software or hardware that needs attention. Having autosave enabled and knowing recovery procedures reduces the impact of unexpected crashes.
At home
Crashes occur when a program encounters an unrecoverable error, such as accessing invalid memory, an unhandled exception, or running out of resources. Freezes can result from deadlocks, infinite loops, or resource exhaustion where the system cannot allocate enough CPU or memory. Operating systems generate crash reports and memory dumps that developers use to diagnose the root cause. Application reliability is measured through metrics like mean time between failures.
At work
Enterprise crash management involves centralized error reporting, automated log collection, and trend analysis across the device fleet. Application performance monitoring tools detect crashes in real time and alert support teams. Crash frequency data informs decisions about software upgrades, hardware refreshes, and vendor escalations. Post-incident reviews for critical system crashes help prevent recurrence and improve resilience.
At home
Technically, crashes manifest as segmentation faults, access violations, stack overflows, or unhandled exceptions depending on the programming language and operating system. Crash dump analysis using debuggers like WinDbg or LLDB reveals the call stack and memory state at the moment of failure. Defensive programming techniques including input validation, exception handling, and resource management reduce crash rates. Watchdog timers and health checks detect frozen processes and trigger automatic recovery.
At work
At the infrastructure level, crash resilience is designed into systems through redundancy, failover mechanisms, and graceful degradation patterns. Chaos engineering practices deliberately inject failures to test system recovery capabilities. Post-mortem processes analyze crash data to identify systemic patterns, often revealing architectural issues that no single crash report would surface. Service level objectives define acceptable crash rates, and breaches trigger engineering investment in reliability improvements.
Real-world examples
At home
Thomas is playing a video game when it suddenly closes and returns him to the desktop with an error message. The game crashed because of a bug in the latest update. He checks online, finds that other players are experiencing the same issue, and waits for the developer to release a fix. His saved progress is intact because the game autosaves regularly.
At work
Sophie, an operations manager, reports that her spreadsheet application freezes every time she opens a specific file. The IT team investigates and discovers the file contains a formula error creating an infinite calculation loop. After fixing the formula, the file opens normally. They also add the incident to their known issues log so future cases can be resolved quickly.
Common confusions
- It's easy to assume a crash means your computer is broken. Crashes are usually caused by software issues and are resolved by restarting the program or applying an update.
- It's often assumed that a freeze requires a full restart. You can usually close just the frozen program through Task Manager without restarting the entire computer.
- One common misunderstanding is that crashes always mean data loss. Many modern applications autosave your work, and recovery options can retrieve unsaved changes after a crash.
For analysts
Crash and freeze reports from users are valuable signals for requirements and quality. If a specific application crashes frequently for certain users, dig into the pattern: is it related to file size, data complexity, or specific features? Include stability requirements in your acceptance criteria, such as maximum acceptable crash rates during user acceptance testing. A system that works perfectly in demos but crashes under real-world conditions has not met its requirements.
History & origin
Software crashes have been a part of computing since the very beginning. Early computers would halt entirely when encountering an error, requiring a manual restart. As operating systems evolved, they introduced process isolation so that a single application crash would not bring down the entire system. Despite decades of improvements in software reliability, crashes and freezes remain a common experience due to the growing complexity of modern software.